
QA Test Case Template Pack
An 11-sheet Excel and Google Sheets workbook: test cases, bug reports, a live dashboard, test plan, RTM and a regression checklist.
$9 one-time
See what’s inside121 copy-paste prompts written for real QA tasks, from test case design and bug reports to Playwright code and flaky test triage. Plus 16 agent-rules files so the AI in your IDE writes tests the way a senior SDET would.
$12 one-time · instant download · secure checkout through Gumroad

$12 one-time · instant download
Secure checkout through Gumroad · TestLinkPro never sees your card details · instant download · no account needed. How buying works
A vague prompt gets a generic answer: five happy-path test cases and an expected result that says “should work correctly”. Each prompt in this pack tells the AI which test design technique to apply, what format to return and what it must not invent, so you get output you can paste into your test management tool, bug tracker or codebase.
Every prompt has a “use when” line and clear {{PLACEHOLDERS}}. 24 prompts include an example output so you know what good looks like.
Drop these into your repository so the AI in your IDE writes test automation the way a senior SDET would: stable locators, no hard waits, independent tests and assertions that actually fail when the feature breaks.
Project rules in .cursor/rules/*.mdc: core standards (always on), Playwright TypeScript, Cypress, Selenium (Java/Python), API tests, flaky-test triage, and a manual @test-review rule.
A CLAUDE.md template plus 3 skills that add the /new-test, /triage-failure and /review-tests commands.
copilot-instructions.md, 2 path-specific .instructions.md files (Playwright tests and API tests) and a reusable prompt file for triaging a failing test.
For other coding agents that read AGENTS.md, plus an install README for all the rule files.


Formats: a 66-page PDF guide, Markdown files (one per chapter plus all-in-one), a plain TXT file, a CSV prompt library you can import into Google Sheets, Excel or Notion, and a Quick Start PDF.
Below is prompt TCD-01 from chapter 2, exactly as it appears in the pack, with its example output. Copy it into ChatGPT, Claude, Gemini or Copilot and replace the placeholders.
Use when: you have a user story with acceptance criteria and need a first set of test cases quickly.
PromptWrite test cases for the user story below.
<story>
{{USER_STORY_AND_ACCEPTANCE_CRITERIA}}
</story>
Requirements:
- Cover every acceptance criterion with at least one positive and one negative test.
- Add edge cases the criteria don't mention but a real user would hit.
- Output a table with columns: ID (TC-{{MODULE}}-001...), Title, Type (Positive/Negative/Edge), Preconditions, Steps (numbered), Test Data, Expected Result, Priority (Critical/High/Medium/Low), AC covered.
- Expected results must be observable: exact messages, URLs, status codes, DB values.
- After the table, list any acceptance criteria that are ambiguous or untestable and suggest a rewrite.| ID | Title | Type | Preconditions | Steps | Test Data | Expected Result | Priority | AC |
|---|---|---|---|---|---|---|---|---|
| TC-RESET-001 | Reset link sent to registered email | Positive | User exists | 1. Open /forgot-password 2. Enter email 3. Click "Send link" | ana@example.com | Message "If an account exists, we've sent a link" shown; email received within 2 min | High | AC1 |
| TC-RESET-004 | Unregistered email gets the same message | Negative | No account for email | Same as TC-RESET-001 | nobody@example.com | Same generic message as TC-RESET-001; no email sent | High | AC1 |
| TC-RESET-007 | Reset link expires after 30 min | Edge | Link generated 31 min ago | Open the link | - | "This link has expired" page with option to request a new one | High | AC3 |
Ambiguous: AC2 "link should be secure" → Suggested rewrite: "Link contains a single-use random token, expires after 30 minutes and becomes invalid after a successful reset."Example outputs use fictional data. Your results will differ, so always review AI output before you use it.
From qa-automation-core.mdc, the always-on Cursor rule that the framework-specific rules build on. The same standards are in the Claude Code, Copilot and AGENTS.md files.
waitForTimeout, sleep, Thread.sleep, cy.wait(<number>)). Wait for a condition instead.
Start a new chat with a prompt from chapter 1 (for example CTX-01), filled in with your product and stack. Every later answer gets more specific.
Copy it from the PDF, Markdown or CSV library and replace every {{PLACEHOLDER}}. Paste long material between the tags provided.
Treat the output as a strong first draft. Check it, run generated code, and keep a human in charge of Pass/Fail and release decisions.
The prompts use real techniques (boundary value analysis, decision tables, state transitions, pairwise and risk-based testing) and include responsible-use guidance: anonymise data first, verify outputs, and never let AI “fix” a test by hiding a real bug.
Current for 2026 tools and standards: Playwright test agents, Cypress cy.prompt, WCAG 2.2 and OWASP Top 10:2025.
Not affiliated with OpenAI, Anthropic, Google, Microsoft, GitHub, Cursor or any tool vendor.
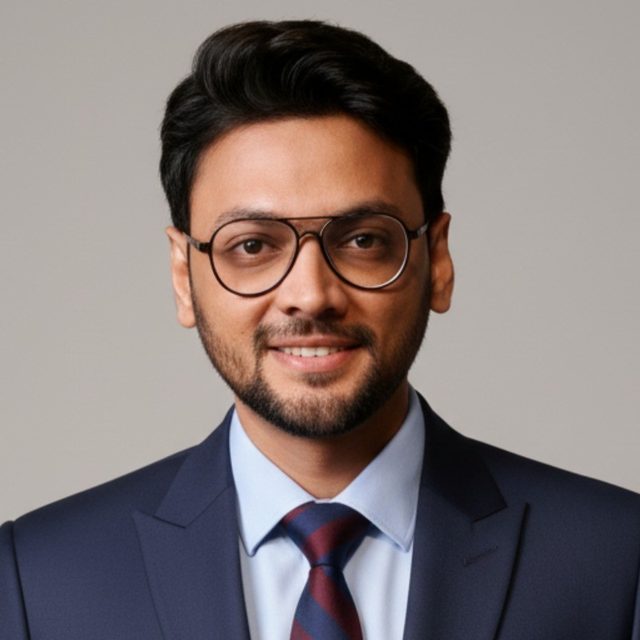
Built by Kamran Ghaffar, a Quality Assurance professional with 10+ years of experience in software quality, test automation and QA leadership.
Any capable assistant: ChatGPT, Claude, Gemini, Microsoft Copilot, or the chat panel in VS Code, Cursor or JetBrains IDEs. The agent-rules files are for Cursor, Claude Code, GitHub Copilot and tools that read AGENTS.md.
No. The prompts work on free plans too. Long inputs (big requirement documents, large code files) work better with models that have larger context windows, which are often on paid plans.
Yes. The UI automation and debugging prompts cover Playwright, Selenium (Java and Python) and Cypress, and there are separate Cursor rules for each. Most of the other chapters (test design, bugs, plans, API, data, regression, accessibility, security) don’t depend on any framework.
Follow your employer’s AI policy. The pack includes a prompt to anonymise logs and tickets before you share them, and guidance on what never to paste (credentials, customer data, confidential code in unapproved tools).
No, and the prompts don’t pretend it will. They speed up the drafting so you have more time for exploration and risk judgement. Always review the output.
Yes. Use the prompts and add the rule files to your company’s or clients’ repositories. You can’t resell or redistribute the pack itself (see LICENSE.txt in the download).
Major updates or new versions of the pack may be released as a separate paid upgrade.
Each pack stands on its own. Together they cover writing tests, working faster with AI, shipping releases and preparing for your next role. Compare all packs.
An 11-sheet Excel and Google Sheets workbook: test cases, bug reports, a live dashboard, test plan, RTM and a regression checklist.
$9 one-time
See what’s inside
249 interview questions with model answers, an editable question bank with a readiness dashboard and study plans.
$19 one-time
See what’s inside
All four packs in one purchase for $39 instead of $59.
$39 one-time
See what’s inside$12 one-time. Instant download from Gumroad, no account needed. Questions first? Email hello@testlinkpro.com.